
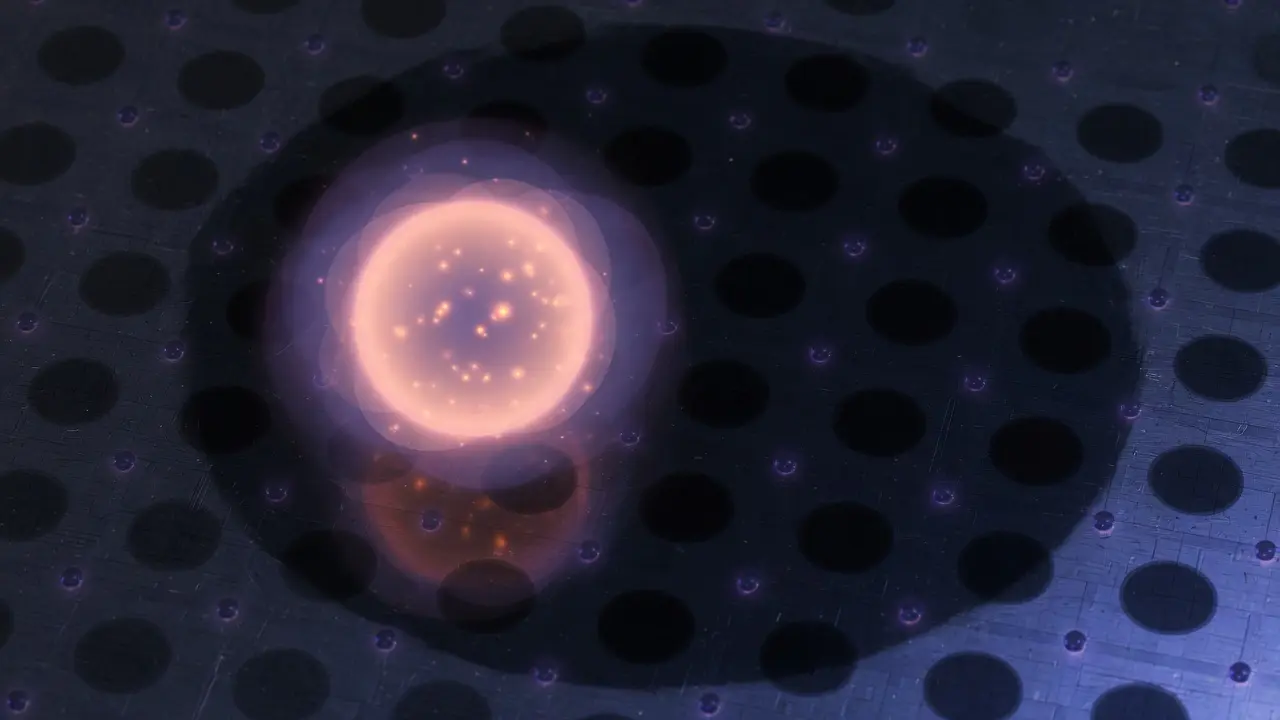
A new reinforcement learning technique constructs disentangling circuits for states with up to 16 qubits, a key step toward more efficient quantum computing. Researchers from the University of Maryland, École Polytechnique Fédérale de Lausanne (EPFL), and the Max Planck Institute for the Physics of Complex Systems developed the approach. The work demonstrates that by accessing only two-qubit reduced density matrices, an agent can learn to control multiqubit entanglement without complete knowledge of the quantum state, making it directly applicable to current noisy intermediate-scale quantum (NISQ) devices.
This method offers a largely unexplored paradigm in quantum interactive dynamics with potential for advances in quantum state preparation and compression. Once trained, it provides circuits from different initial states without further optimization. Analyzing optimal disentangling protocols, the researchers report a general circuit to prepare an arbitrary 4-qubit state using at most 5 two-qubit (10 CNOT) gates.
Two-Qubit Reduced Density Matrices Guide Disentanglement
Observations comprising all symmetrized two-qubit reduced density matrices enable a new approach to controlling multiqubit entanglement, bypassing the need for complete quantum state knowledge. This method scales polynomially with the number of qubits, a significant reduction from the exponential scaling of traditional tomography techniques. By focusing on these localized measurements, the system simplifies the computational burden of assessing and manipulating complex quantum states.
The reduced density matrices focus on subsystems containing only two qubits, discarding information about the remaining qubits to achieve this efficiency. This process allows the agent to autonomously learn disentangling protocols without prior knowledge of the initial quantum state.
The agent’s ability to function with limited information is particularly relevant for near-term intermediate-scale quantum (NISQ) devices, where accessing complete state information is often impractical. “The RL agent only has access to locally measurable two-qubit reduced density matrices,” the paper notes, highlighting the direct applicability of this technique to current hardware limitations. While other algorithms aim for perfect disentanglement, this approach prioritizes finding effective protocols even with the constraints of locally optimal gates.
Comparisons to existing methods reveal discrepancies for larger, more complex states, likely stemming from this difference in optimization goals. The research demonstrates that the agent can identify and exploit the entanglement structure within multi-qubit states, constructing circuits with minimal gate resources. The agent’s learned disentangling protocols also exhibit robustness to typical errors encountered in NISQ devices, suggesting a pathway toward more resilient quantum computations. The method’s efficacy has been demonstrated on states containing up to 16 qubits.
Deep Reinforcement Learning for Multiqubit State Control
The agent’s architecture uses a permutation-equivariant transformer, allowing it to autonomously recognize and adapt to qubit permutations within a given quantum state, a capability not typically found in standard disentangling algorithms. This adaptation is important because qubit order does not inherently define the entanglement structure, and the agent’s ability to account for this enhances the efficiency of the disentangling process.
The research extends beyond simply achieving disentanglement. It investigates whether exploiting partial knowledge of a quantum state can provide an advantage in quantum control tasks. The team employed a reinforcement learning approach, specifically an actor-critic algorithm, to construct circuits designed to disentangle states containing up to 16 qubits.
Analysis of the resulting circuits for 4- and 5-qubit states revealed strong correlations between consecutive gates and among the qubits involved, suggesting the agent effectively identifies and exploits the underlying entanglement structure. This ability to learn disentangling protocols with minimal gate resources demonstrates a promising pathway toward more efficient quantum state preparation and manipulation on near-term devices.
Permutation-Equivariant Transformers Identify Qubit Permutations
The agent’s architecture incorporates a permutation-equivariant transformer, enabling autonomous identification of qubit permutations within a quantum state and subsequent adjustment of the disentangling protocol. The transformer’s design means the system can adapt to variations in qubit labeling without compromising performance, a feature important for scalability. These correlations suggest the agent isn’t simply applying gates randomly, but instead learning to target specific entanglement pathways within the system.
RL Agent Training and Disentangling Circuit Generation
The policy network’s success in discerning patterns within these partial observations suggests a novel approach to managing complexity in quantum systems. Resource scaling presents a challenge as system size increases, with the computational demands for both the agent’s learning process and the environment’s quantum simulations growing exponentially. The paper notes this exponential scaling reflects the inherent complexity of optimal disentangling circuits, not a limitation of the algorithm itself, but it still prolongs training and requires substantial computational resources.
Comparisons reveal the forward and backward passes of the reinforcement learning agent demand significantly more resources than applying a single two-qubit gate within the simulator, highlighting the computational cost of the learning process. Demonstrations on a trapped-ion quantum computer involved preparing the system in four distinct initial states, Bell-Bell, GHZ, W, and a shallow circuit, to validate the agent’s performance in real-world conditions.
Visualizations of the inferred gates and corresponding action probabilities show the agent correctly identifies qubit pairs for disentanglement with minimal steps, as seen in the accompanying video. The agent’s learning progression is observable through stages focused on isolating qubit pairs, achieving full disentanglement and minimizing the number of gates required, demonstrating a clear evolution of its policy.
For 4-qubit systems, the agent significantly reduced the average number of two-qubit gates needed to disentangle fully Haar-random states.
NISQ Device Applicability via Local Information
This capability stems from a permutation-equivariant transformer architecture, allowing the system to recognize and account for qubit orderings during circuit construction. This automated adjustment is critical for handling the inherent variability of quantum states and optimizing disentanglement efficiency. This experimental verification emphasises the practicality of relying solely on locally measurable two-qubit reduced density matrices for quantum control. The researchers also explored the broader implications of this adaptive algorithm, noting its potential to reduce circuit size, a major advantage not previously addressed in the field.
The concept of learning entanglement distribution and using it to improve disentangling circuits, they suggest, is not limited to superconducting qubits or trapped ions. The methodology extends to quantum optics, where entangling gates are implemented via beam splitters, and can be generalized to higher-dimensional qudit systems.
To quantify disentanglement progress, the team defined a cost function based on average single-qubit entanglement, using the von Neumann entropy, though other measures like Renyi entropies or Fisher information could also be employed. Analyses of noisy superconducting qubits and trapped ion platforms further validated the agent’s robustness, revealing its potential for application across diverse quantum computing architectures. “However, this quantity is not continuous and therefore not directly amenable to gradient-based optimization,” the researchers explain, detailing the need for a smooth cost function to facilitate the learning process.
Entanglement Structure Exploitation by the RL Agent
The agent’s ability to discern entanglement structure extends to random states lacking obvious patterns, allowing it to minimize gate usage during disentanglement. Benchmarking against both random and greedy agents, the reinforcement learning approach consistently reduces the average number of gates needed to reach a defined entanglement threshold, a key metric for evaluating quantum circuit efficiency. This performance suggests the algorithm is not simply memorizing solutions but identifying underlying principles of entanglement distribution.
Beyond raw gate count, the learned disentangling circuits reveal internal correlations, indicating the agent is not operating as a black box. Comparisons to a deterministic algorithm implemented in Qiskit v0. 20. 0-v1. 0. The RL agent consistently outperforms this method across systems of 4, 5, and 6 qubits, implying a potential role as a pre-transpilation routine to optimize quantum circuits.
Extending the analysis to larger systems, the agent was benchmarked on weakly entangled subsystems of 12- and 16-qubit Haar-random states, maintaining its efficacy. The ability to identify and exploit entanglement structure is not limited to randomly generated states. The agent also performs well on fully-entangled states that are not Haar-random, indicating a broader applicability. “As soon as the initial state possesses a non-trivial entanglement structure, using the RL agent as a pre-transpilation routine results in an advantage for the three considered system sizes,” the researchers state, highlighting the potential for practical improvements in quantum computation.
Resilience of Trained Agents to Quantum Noise
The developed reinforcement learning agent demonstrates an ability to function effectively even with imperfect data, an important step toward practical quantum computation. Analyses reveal the agent tolerates moderate levels of both shot noise and environmental noise, despite initial training in a noise-free simulation environment, highlighting a key advantage of reinforcement learning algorithms. This resilience stems from the agent’s capacity to discern and use measurable partial information about a quantum state, reducing the number of control operations required for disentanglement.
Beyond simulation, the trained agent successfully disentangled nontrivial states on a real trapped-ion quantum processor, confirming robust transfer from the digital to physical realm. This deployment shows the algorithm’s adaptability to realistic, noisy hardware, a significant hurdle for many quantum control methods. The team reports a general circuit to prepare an arbitrary 4-qubit state using at most 5 two-qubit (10 CNOT) gates.
Spatial correlations appear among qubits, while temporal correlations are observed between consecutive gates applied, indicating a sophisticated understanding of quantum dynamics. The researchers note, “the trained agent successfully recognizes local entanglement structures and uses them to construct shorter protocols.” The code used in this work is publicly available, including a Jupyter notebook allowing users to test the agent on custom states, introduce mid-circuit perturbations and monitor the attention heads of the underlying transformer network.
Disentangling Protocols and 10 CNOT Gate Limit
The developed reinforcement learning agent constructs quantum circuits for arbitrary 4-qubit states using at most 5 two-qubit (10 CNOT) gates. This efficiency stems from the agent’s ability to identify and exploit existing entanglement structure within multi-qubit systems, rather than attempting to build entanglement from scratch. Strong correlations exist between the sequence of gates applied and the specific qubits targeted.
The agent’s resilience to noise further enhances its practicality for near-term quantum devices. Benchmarking demonstrates the approach effectively minimizes gate resources needed for disentangling protocols, an essential step toward scalable quantum computation.
👉 More information
🗞 Reinforcement learning to disentangle multiqubit quantum states from partial observations
✍️ Pavel Tashev, Stefan Petrov, Matthew T. Diaz, Friederike Metz, Alaina M. Green, Norbert M. Linke and Marin Bukov
🧠 DOI: http://link.aps.org/doi/10.1103/byp8-29dg

See today’s quantum computing news on Quantum Zeitgeist for the latest breakthroughs in qubits, hardware, algorithms, and industry deals.