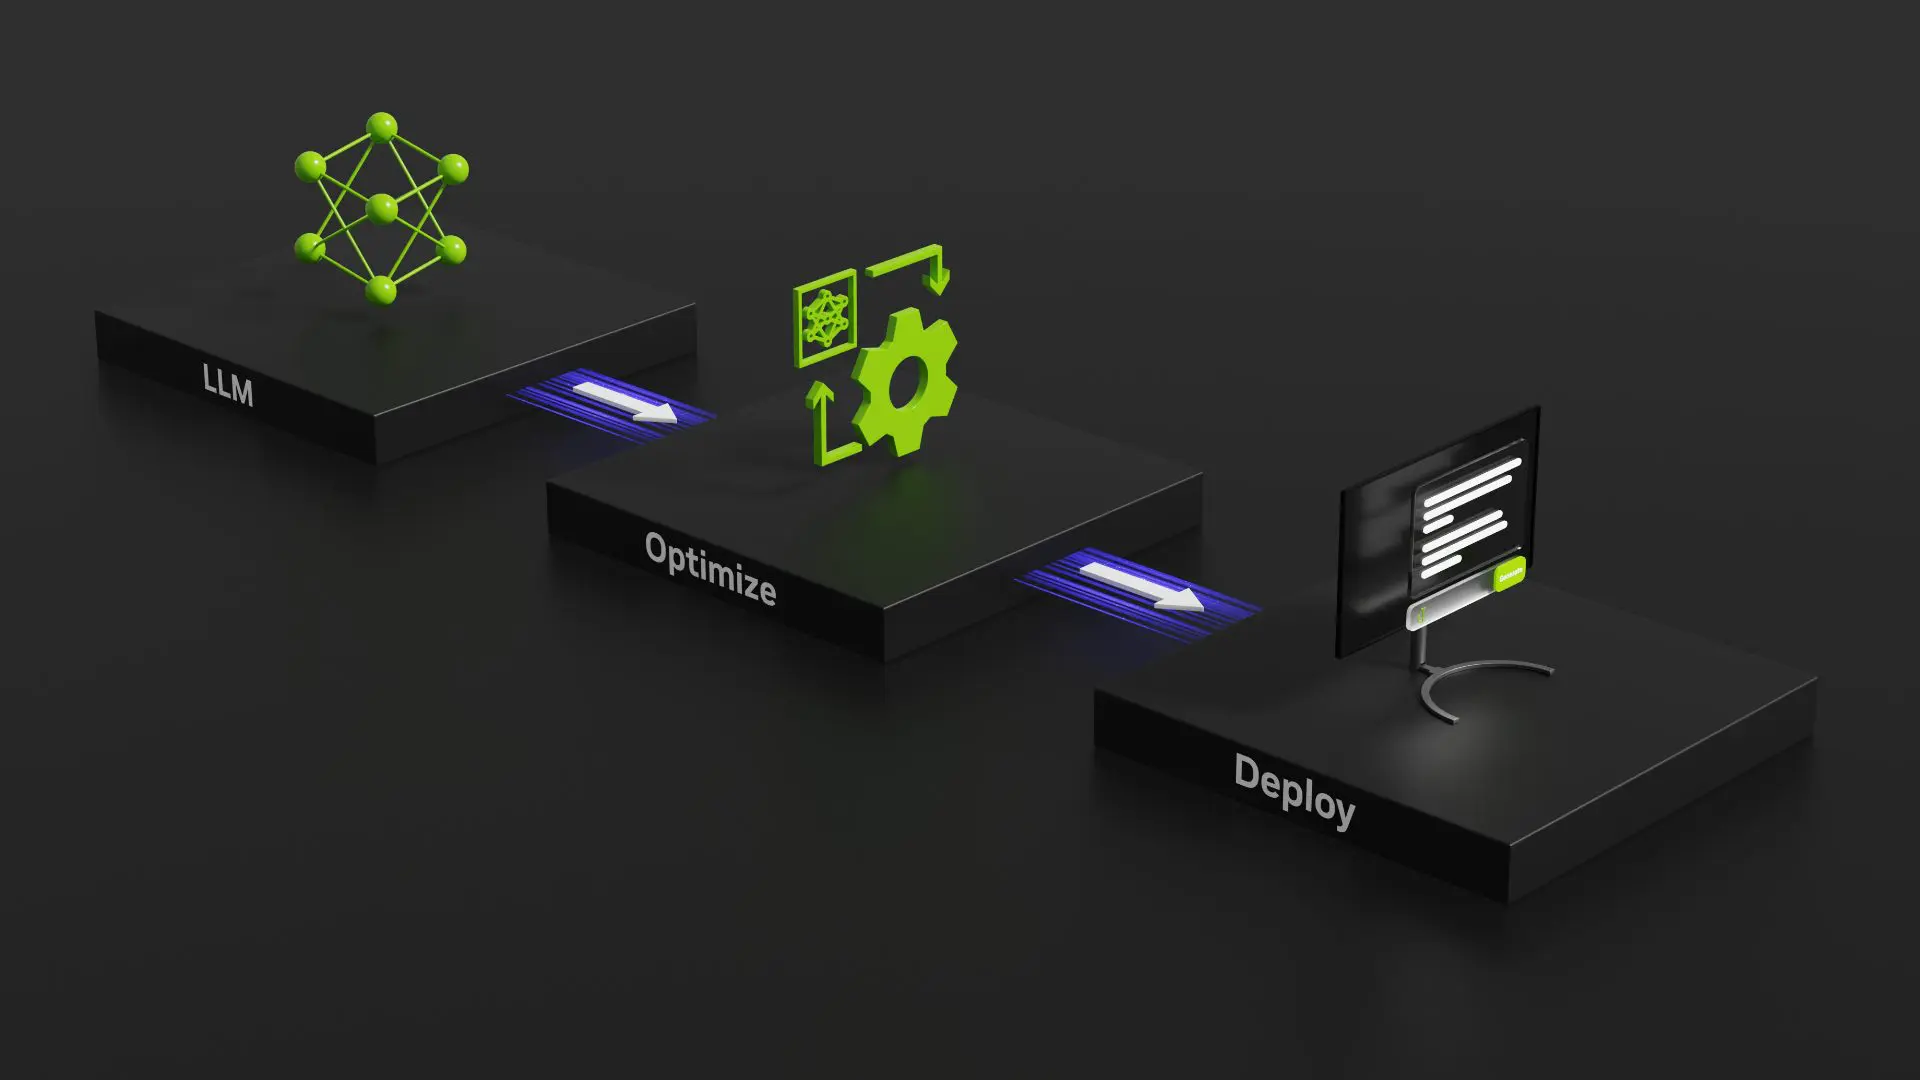
NVIDIA TensorRT Edge-LLM completed the MLPerf Edge Agentic benchmark running Qwen3.6-27B on a single Jetson AGX Thor Developer Kit in 24 minutes and 36 seconds. This result achieved 52.33 tokens per second, a 6.4x speedup compared to the llama.cpp reference submission’s 2 hours and 37 minutes. The benchmark tests long-context processing with a workload of 1,007 generated turns and input length reaching approximately 23.5K tokens, demanding efficient processing of extended conversational histories for AI agents moving to edge devices.
TensorRT Edge-LLM Achieves 6.4x Speedup on MLPerf Agentic
The TensorRT Edge-LLM submission completed the MLPerf Edge Agentic benchmark using Qwen3. Achieving an output throughput of 52.33 tokens per second, the system demonstrated a median time to first token of 247.12 milliseconds and a median time per output token of 14.68 milliseconds, MLPerf says. This performance translated to a BFCL overall accuracy of 87.94% on the complex Agentic workload.
The MLPerf Edge Agentic benchmark assesses an AI model’s ability to correctly select functions, generate valid arguments, and refrain from unnecessary tool use within a multi-turn conversational loop. The benchmark incorporates tool results into the ongoing conversation before each subsequent model request, testing long-context processing capabilities.
Compared to a reference run utilizing llama.cpp and Qwen3.6-27B with quantization on the same hardware, TensorRT Edge-LLM reduced completion time by 6.4x, finishing the workload in 24 minutes and 36 seconds against the reference’s 2 hours and 37 minutes. Further optimization came from employing a tree-based multi-token prediction method; compared with a linear MTP utilizing three draft steps, this approach yielded approximately a 40% gain in decoding performance for this specific workload.
The implementation details, including model export settings and TensorRT engine build commands, are available on the release/0.9.1-mlpinf branch of the TensorRT Edge-LLM repository. Luxiao Zheng, Palanivel Guruva reddiar, Maximilien Breughe, Zhihan Jiang, Zhijia Liu and Lin Chai contributed to this work, and the team expressed thanks to the MLCommons community for developing the Edge Agentic benchmark and endpoint harness, according to MLPerf. “inference-endpoint benchmark from-config \ –config” is a command used in the implementation process.
Qwen3.6-27B Optimization with NVFP4 and Quantization
Reducing both the weight and activation sizes demonstrably boosts decoding performance by lessening the memory footprint of the kernels, a strategy employed in optimizing the Qwen3.6-27B model for the MLPerf Edge Agentic benchmark. NVIDIA’s TensorRT Edge-LLM implementation utilizes NVFP4 for both weights and activations, extending to the language-model head, alongside FP8 for the KV cache, to achieve substantial gains in speed and efficiency.
This approach uses the 4-bit floating-point format supported by the NVIDIA Blackwell GPU within the Jetson AGX Thor platform, enabling optimized kernel acceleration while maintaining the accuracy demanded by the MLPerf standard, the firm reports. The reduced model size also preserves more of the Jetson AGX Thor’s 128 GB unified memory for handling long context lengths, speculative decoding, and other application workloads. Developers can begin with a published, calibrated Qwen3.6-27B NVFP4 checkpoint, streamlining the deployment process.
KV Cache Reuse for Long-Context Agent Interactions
Efficient long-context processing within agent interactions relies heavily on managing the key-value (KV) cache, and NVIDIA TensorRT Edge-LLM uses this through a novel reuse strategy. The system identifies and restores cached attention KV pages corresponding to reusable prompt prefixes across consecutive agent turns, significantly reducing redundant computation. The optimization addresses 5K tokens, demanding substantial long-context handling capabilities. This optimization complements tree-based multi-token prediction by addressing computational costs at different stages; KV cache reuse minimizes pre-generation expenses, while multi-token prediction reduces the number of steps during actual generation.
Approximately 96% of prompt tokens were served from the hot cache during the benchmark, demonstrating the effectiveness of this technique. The runtime only needed to prefill around 0.5 million of the total 13.6 million prompt tokens across all turns, a substantial reduction in processing load.
Qwen3.6, a hybrid model architecture, further benefits from this approach as the runtime also restores the recurrent state and partial KV-page state needed for correct execution. This method avoids repeatedly prefilling the shared conversation history with each turn, a process that becomes increasingly expensive as the dialogue extends.
“Without reuse, the model must prefill the shared history again on every turn,” explains the documentation, highlighting the core problem this technique solves. The ability to efficiently manage and reuse the KV cache is therefore critical for scaling agentic AI performance on edge devices, enabling more complex and sustained interactions without sacrificing speed or responsiveness.
Tree-Based Multi-Token Prediction Accelerates LLM Decoding
Tree-based multi-token prediction (MTP) further accelerated large language model decoding during the MLPerf Edge Agentic benchmark, contributing to a 6.4x performance gain over the llama.cpp reference submission. Unlike standard autoregressive decoding which generates one token per model invocation, MTP employs a draft model to predict multiple future tokens for simultaneous verification by the target model.
NVIDIA’s TensorRT Edge-LLM implementation extends this approach with a tree-based structure, organizing high-probability candidate tokens into a branching hierarchy rather than a linear sequence. The optimization works in concert with KV cache reuse, minimizing redundant computation across the 1,007 turns of the agentic AI performance workload.
The runtime prefills only the new portion of the conversation, serving approximately 96% of prompt tokens from a hot cache, and requiring prefilling of only around 0.5 million of the total 13.6 million prompt tokens. Researchers can clone the repository and initialize its submodules using standard git commands, as detailed in the provided documentation. This open access approach facilitates reproducibility and further development of optimized LLM inference techniques, potentially accelerating the deployment of agentic AI systems on edge devices.
See today’s quantum computing news on Quantum Zeitgeist for the latest breakthroughs in qubits, hardware, algorithms, and industry deals.